We’ll explore how to leverage a corpus of 1,800 articles (~1.8 million words, comparable in volume to A Song of Ice and Fire) to build an AI-driven discovery platform that makes reading, exploration, and print publication smarter and more meaningful.
The central challenge is not merely searching text, but transforming a monumental chronological archive into a living knowledge base:
- 1. 37 legacy Word 97 files
- 2. 1,800 clean Markdown files
- 3. AI-generated metadata & scores
- 4. Semantic search & discovery
- 5. Curated print anthologies (LaTeX)
From Word 97 lecture transcripts to structured Markdown
These articles were originally transcripts of lectures recorded since the early 2000s. For years, they existed only as 37 separate Word files (some created in Word 97), each identified only by its date. They were never published online, but gathered once a year into printed booklets, directly exported from Word, with minimal formatting and uneven layout.
Before: trapped in legacy files
Word 9737 monolithic Word files identified only by date, with uneven formatting and zero searchability, exported once a year into raw printed booklets.
After: structured Markdown corpus
Living knowledge1,800 standalone Markdown files with YAML frontmatter, AI-generated titles, section headings, SEO summaries, and semantic tags ready for discovery.
Using a custom Python script and Pandoc, the collection was converted into individual Markdown files, one per lecture. An AI system then analyzed each text to create meaningful titles, add intermediate headings, and generate concise SEO descriptions: transforming a chronological archive into a structured, readable, and accessible body of work. The full workflow for converting Word files into SEO-optimized web pages is described in turn Word files into SEO-optimized web pages with AI.
- 37 legacy Word files
- Python + Pandoc extraction
- 1,800 individual .md files
- AI title & heading generation
- Structured discovery corpus
Objective: building an AI-enabled knowledge platform from 1,800 articles
The goal is to transform a vast, heterogeneous collection of articles into a structured, AI-enabled knowledge platform.
1. Structure layer
FoundationOrganize the heterogeneous archive into 1,800 clean, version-controlled Markdown files with standardized YAML frontmatter.
2. Discovery layer
EnrichmentEnrich each lecture with thematic tags, Gaussian-normalized relevance scores, full-text indexation, and vector embeddings.
3. Interaction layer
AssistanceEnable conversational exploration, terminology clarification, contextual reading recommendations, and automated print curation.
The editorial principle: Make historical articles discoverable and approachable without losing the depth, subtlety, or authentic voice of the original teachings.
The end-to-end system architecture spans five connected layers:
- Source: Historical lectures
- Content: Markdown + frontmatter
- Discovery: Search, themes & scores
- AI: Questions & recommendations
- Publishing: Web & print anthologies
Analysis and cleaning
Before AI can meaningfully process the corpus, the data must be clean and consistent:
- 1. Deduplicate repeated lectures
- 2. Normalize formatting & timestamps
- 3. Quality checks for incomplete texts
- 4. Enforce terminology consistency
- Deduplication: Identify repeated articles and remove redundant content across files.
- Formatting normalization: Standardize headers, timestamps, and text encoding.
- Quality checks: Flag incomplete or corrupted articles for human review.
- Consistency enforcement: Align style, terminology, and structural headings for machine readability.
Infrastructure before AI: AI does not magically fix poor data quality. Cleaning and normalization form the indispensable foundation for reliable metadata, dependable indexing, and trustworthy AI interaction.
Metadata and tagging
Metadata transforms a large corpus into a discoverable and analyzable knowledge base:
Describe
SEO & WebGenerate titles, meta descriptions, and keyword sets optimized for search engines and web-based exploration.
Classify
Thematic taxonomyAutomatically assign pedagogical themes: meditation, cause and effect, lineage, training, and daily life.
Rank
Relevance scoresAssign interest scores and thematic relevance indicators based on user priorities and contextual intensity.
Connect
Cross-linkingInsert cross-references, summaries, and definitions for technique-related terminology to improve searchability.
AI assists here by reading each article and suggesting thematic tags or highlights while maintaining consistency across the entire collection.
Indexing and search
A robust indexing system enables fast, accurate retrieval, moving progressively from exact matches to conceptual connections:
- 1. Keyword: 'What says X?' (full-text)
- 2. Theme: 'What discusses X?' (taxonomy)
- 3. Semantic: 'What means related to X?' (embeddings)
- 4. Graph: 'What else connects to X?' (cross-links)
- Full-text search: Index content to allow keyword-based queries across 1,800 texts.
- Thematic navigation: Enable filtering by topics, scores, or temporal context.
- Semantic search: Use embeddings or vector search to capture meaning beyond exact keywords, letting users find related concepts even if phrased differently.
- Cross-linking: Automatically connect related articles to create a web of knowledge that mirrors article interconnections.
This ensures that users can explore the corpus efficiently, whether seeking a specific lesson or discovering related concepts.
Interactive AI layer
The AI layer transforms static content into an intelligent, interactive discovery platform:
Recommend
ExplorationSuggest articles or themes based on user interests or previous reading paths.
Explain
ClarificationSummarize complex teachings or provide background on lineage and philosophical terminology.
Converse
DialogueAllow users to ask questions, clarify concepts, or explore nuances dynamically.
Connect
InsightsGenerate summaries, highlight patterns, and identify frequently referenced masters or concepts.
Preservation of integrity: The original lecture transcripts remain intact and untouched. AI-generated metadata, embeddings, and summaries serve strictly as an enrichment layer to guide readers back to the source text.
Deploying the AI discovery platform for web and API access
Finally, the platform is designed as an extensible content platform rather than a collection of one-off scripts:
- Clean corpus infrastructure
- Discovery & metadata layer
- Interfaces: Web portal, REST API & Print compilers
- Web interface: User-friendly dashboards for browsing, filtering, and exploring articles.
- API access: Allow other applications or AI systems to query the corpus programmatically.
- Scalability: Ensure smooth operation even as new articles or supplementary materials are added.
- Preservation of integrity: Maintain original text alongside enriched metadata to honor the authenticity of the articles.
Automated thematic scoring of Markdown files with GPT
We can use a Python script to automate the evaluation and enrichment of Markdown files by assigning a semantic score related to any theme, for instance, daily life.
The scoring process operates in three explicit stages:
- 1. AI evaluation (raw score 1–10)
- 2. Gaussian normalization (rebalance)
- 3. Write back into YAML frontmatter
1. AI-based Evaluation
Each .md file is read and sent to an OpenAI model. The model assigns a raw score from 1 to 10, estimating how strongly the text relates to the target theme.
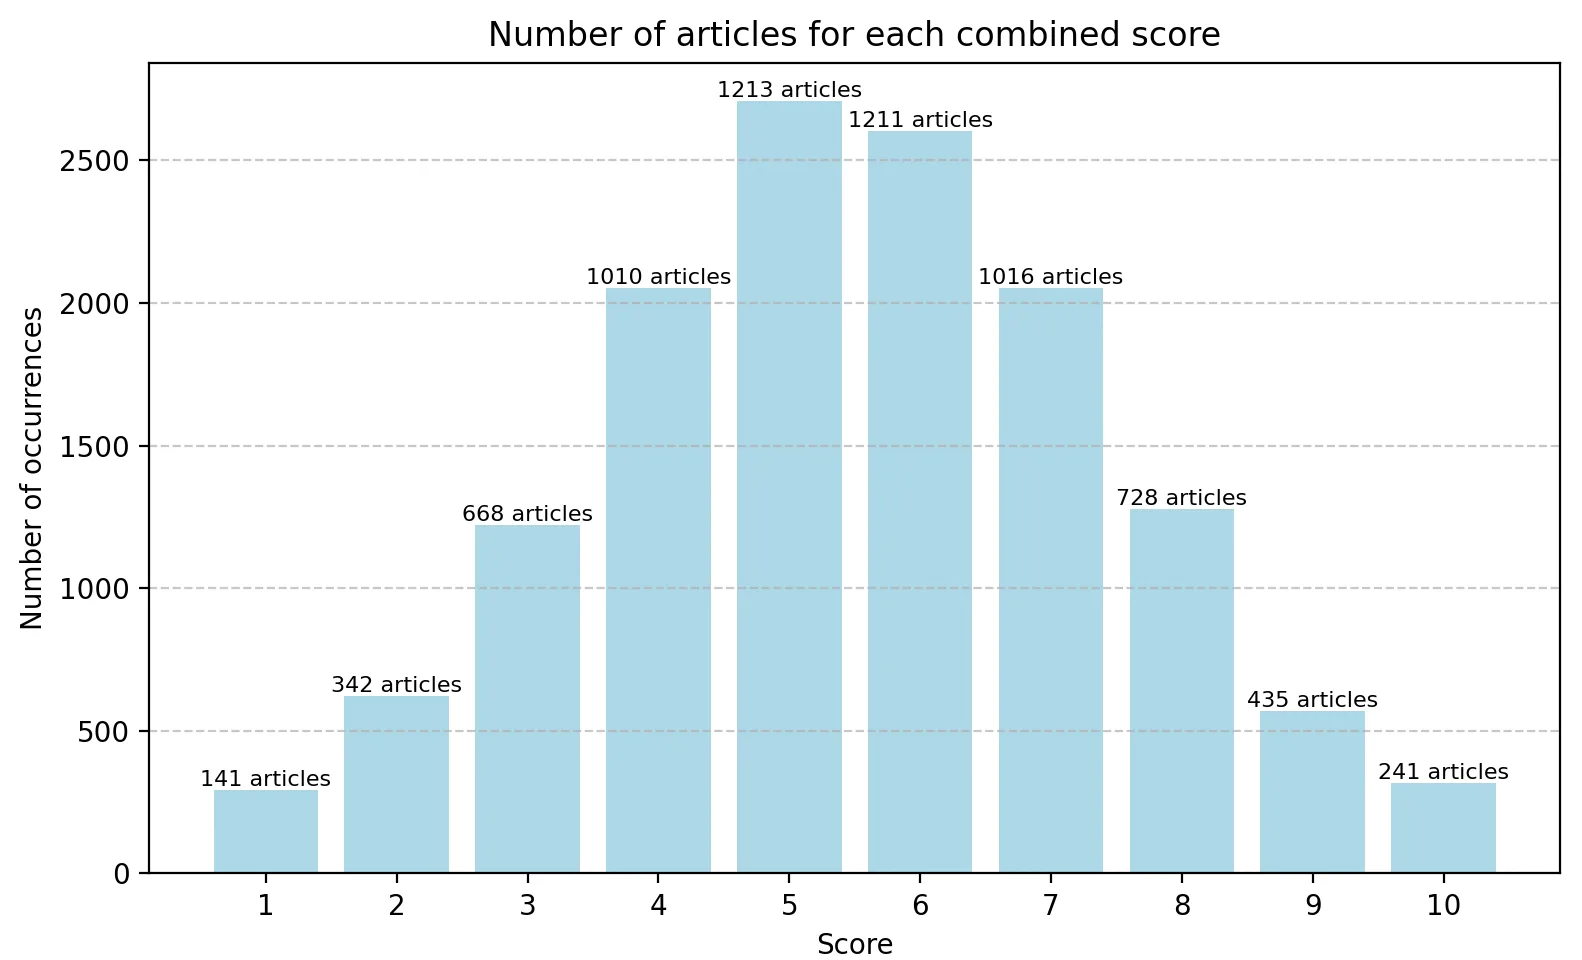
2. Gaussian Normalization
To ensure a smooth and realistic distribution of results, the raw scores are rebalanced using a Gaussian (normal) curve, spreading the final values evenly across the 1–10 range. This avoids clusters of identical scores and makes large-scale data more insightful.
Normalization vs. underlying truth: There’s no law that thematic relevance is normally distributed: for a corpus built around core themes, it may genuinely be bimodal or heavily skewed. Forcing raw scores onto a bell curve spreads them out for browsing, but it manufactures gradations that may not exist and flattens real clusters. Normalize for presentation, but keep raw scores too: the raw distribution reveals the true density of the corpus.
3. Frontmatter Update
The script then writes the final score back into each file’s YAML frontmatter as a new or updated field.
Example: AI-generated metadata record
The metadata for this article was generated from an AI-assisted analysis of hundreds of articles. By identifying recurring themes of awareness, balance, and mindful attention, the AI distilled key insights into how stillness can nurture clarity and calm in everyday life:
title: The Power of Stillness – Deepening Awareness Through Mindful Sitting
sourceLanguage: en
description: Explore how mindful sitting cultivates presence, clarity, and balance in everyday life through sustained attention and inner calm.
lastUpdated: 2009-10-31T11:00:00Z
wordCount: 1586
keywords:
- Mindfulness
- Meditation
- Awareness
- Focus
- Presence
- Inner Calm
- Clarity
- Balance
- Attention
- Well-being
interest_score: 10
daily_life: 8
mindful_posture: 8
intentional_action: 7
continuity_of_practice: 10
From text file to structured record: Each article remains readable Markdown, but now carries machine-readable keywords, timestamps, word counts, and multi-thematic scores that power programmatic curation.
From Markdown to LaTeX: automating the creation of various anthologies
The curation problem: No one could realistically read 1.8 million words of articles in print: even a skilled reader would need about 120 hours—roughly two full weeks of non-stop reading—to get through them all. Since the full corpus is available online, the real challenge is curation: selecting and assembling themed anthologies tailored to reader interests.
A Python script automates the conversion and assembly of Markdown articles into a single, beautifully formatted LaTeX book, ready to compile with XeLaTeX or LuaLaTeX on Overleaf.
It performs the entire workflow in three stages:
- 1. Markdown cleaning & Pandoc conversion
- 2. Chapter tracking in .chapters_list.txt
- 3. main.tex assembly & XeLaTeX/LuaLaTeX compile
- Markdown Cleaning and Conversion
Given a Markdown file, the script extracts its title from the YAML frontmatter, removes HTML markup and Markdown links, and converts the text into LaTeX using Pandoc. Each
.mdfile becomes a clean, self-contained.texchapter with a proper\chapter{Title}heading.
-
Chapter Management Every generated chapter file is recorded in a hidden list (
.chapters_list.txt). This ensures that chapters are automatically tracked and appear in the correct order when the book is rebuilt. -
Book Assembly The script then reconstructs a master file,
main.tex, combining a custom-themed LaTeX preamble (Garamond typography, A5 format, glossary of technique-related terms),\input{}references for each chapter, and a closing section with a glossary of keywords.
Engineering meets craftsmanship: The automation does not replace book design. It bridges editorial selection and typography, compiling hundreds of standalone Markdown files into unified, publication-quality physical volumes.
Outcome: a scalable AI-powered publishing platform for deep reading
The result is a unified platform where one structured corpus powers two complementary discovery and publishing streams:
Digital discovery platform
Web & APIFull-text indexing, multi-thematic filtering, vector embeddings, and an interactive conversational assistant for continuous online exploration.
Curated print publishing
LaTeX & BooksAutomated threshold selection, deduplication against published books, Pandoc chapter conversion, and LaTeX compilation into elegant A5 print anthologies.
Readers are offered a way to rediscover meaningful content through both digital exploration and carefully crafted print editions, bridging technology and editorial quality. To see how this same corpus becomes a living daily knowledge flow, read transforming a corpus of 7,000 pages into living knowledge.